NOW BUZZING 무역박람회에 AI 비서와 로봇이 등장한 … · 안경이 스니커즈가 되는 중, 진스의 승부… · CGV 10월 특별상영관 라인업, 영화·…◆
JELIBI
⌕ SUBSCRIBE
SEOUL · DAILY · ISSUE No.341 WE TRIED IT · THE PICK · BEHIND IT 2026.11.14 · SAT
JELIBI
⌕ SUB
Beauty Body Gadget Bites Buzz World
HOME/GADGET/BEHIND IT
GADGET BEHIND IT · 5 MIN READ

Meta, 텍스트·3D 세그멘테이션 AI SAM 3/3D 공개
JD 젤리비 편집국 · 2026.08.05 SHARE · COPY LINK

무슨 발표인가

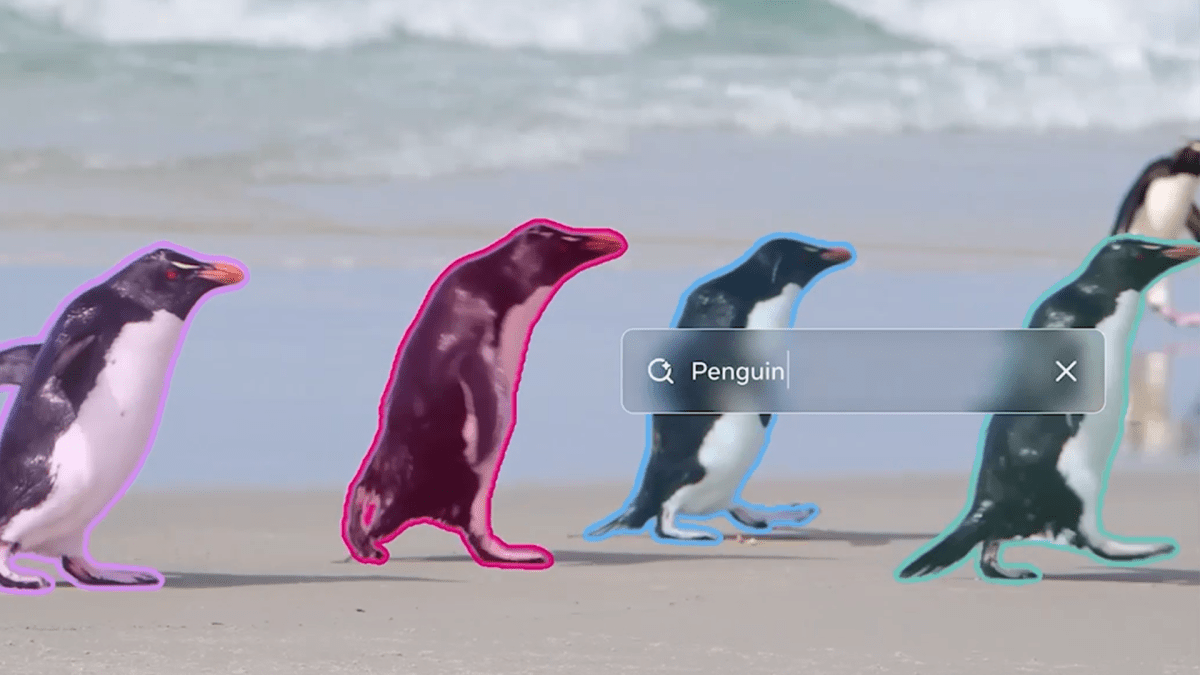
  • SAM 3으로 텍스트 프롬프트 기반 객체 감지·추적
  • SAM 3D로 단일 이미지 기반 3D 재구성
  • Segment Anything Playground에서 실험 가능

원문 (영어)

Today, we’re excited to announce SAM 3 and SAM 3D, the newest additions to our Segment Anything Collection . SAM 3 enables detection and tracking of objects in images and video using text and visual prompts, and SAM 3D enables 3D reconstruction of objects and people based on a single image.

You can experiment with both models now on our new platform, Segment Anything Playground. These advancements will help us build the next generation of creative media tools, simplifying video editing and giving us new ways to interact with and understand the visual world.

Say What You Mean SAM 3 makes it easy to detect, segment, and track objects in images and video — functions that can be used to edit and transform videos and images. SAM 1 and 2 supported segmentation based on visual prompts, and now, SAM 3 enables you to segment using detailed text prompts describing the objects you want to segment.

Traditionally, AI models have struggled to link language to specific visual elements in images or videos. Existing models typically have a fixed set of text labels and are able to segment simple concepts like “bus” or “car,” but struggle with more detailed concepts like “yellow school bus.”

SAM 3 overcomes this limitation, accepting a much larger range of text prompts. Type in “red baseball cap” and SAM 3 will segment all matching objects in the image or video. SAM 3 can also be used with multimodal large language models to understand longer, more complex text prompts, like “people sitting down, but not wearing a red baseball cap.”

We’re using SAM 3 to build a new generation of creative media tools. In Edits, our video creation app, we will soon introduce effects that creators can apply to specific people or objects in their videos.

원문: Meta Newsroom — "New Segment Anything Models Make it Easier to Detect Objects and Create 3D Reconstructions" (2026-08-05) 공식 원문: https://about.fb.com/news/2025/11/new-sam-models-detect-objects-create-3d-reconstructions/

#Meta Newsroom
THE JELIBI BRIEF

A small team that reads too much internet so you don't have to.

SUBSCRIBE →
GADGET

삼성헬스 수면 코칭 업데이트, 데이터 요구사항 완화

GADGET

오픈소스 취약점 스캔 서비스 OSS Scanner 무료 출시

GADGET

메타, 싱가포르 장애인을 위해 AI 안경 1000개 기부

← GADGET BEHIND IT

Meta, 텍스트·3D 세그멘테이션 AI SAM 3/3D 공개

젤리비 편집국·2026.08.05·5 MIN
IN THIS PIECE
무슨 발표인가 원문 (영어)

무슨 발표인가

  • SAM 3으로 텍스트 프롬프트 기반 객체 감지·추적
  • SAM 3D로 단일 이미지 기반 3D 재구성
  • Segment Anything Playground에서 실험 가능

원문 (영어)

Today, we’re excited to announce SAM 3 and SAM 3D, the newest additions to our Segment Anything Collection . SAM 3 enables detection and tracking of objects in images and video using text and visual prompts, and SAM 3D enables 3D reconstruction of objects and people based on a single image.

You can experiment with both models now on our new platform, Segment Anything Playground. These advancements will help us build the next generation of creative media tools, simplifying video editing and giving us new ways to interact with and understand the visual world.

Say What You Mean SAM 3 makes it easy to detect, segment, and track objects in images and video — functions that can be used to edit and transform videos and images. SAM 1 and 2 supported segmentation based on visual prompts, and now, SAM 3 enables you to segment using detailed text prompts describing the objects you want to segment.

Traditionally, AI models have struggled to link language to specific visual elements in images or videos. Existing models typically have a fixed set of text labels and are able to segment simple concepts like “bus” or “car,” but struggle with more detailed concepts like “yellow school bus.”

SAM 3 overcomes this limitation, accepting a much larger range of text prompts. Type in “red baseball cap” and SAM 3 will segment all matching objects in the image or video. SAM 3 can also be used with multimodal large language models to understand longer, more complex text prompts, like “people sitting down, but not wearing a red baseball cap.”

We’re using SAM 3 to build a new generation of creative media tools. In Edits, our video creation app, we will soon introduce effects that creators can apply to specific people or objects in their videos.

원문: Meta Newsroom — "New Segment Anything Models Make it Easier to Detect Objects and Create 3D Reconstructions" (2026-08-05) 공식 원문: https://about.fb.com/news/2025/11/new-sam-models-detect-objects-create-3d-reconstructions/

#Meta Newsroom
THE JELIBI BRIEF

A small team that reads too much internet so you don't have to.
SUBSCRIBE →
MORE IN BEHIND IT
CJ프레시웨이, 세종파닭 팝업스토어 운영·지역 상생 추진삼성헬스 수면 코칭 업데이트, 데이터 요구사항 완화CGV 10월 특별상영관 라인업, 영화·공연·애니 풍성CGV, 서울 도심 주요 거점서 불꽃축제 영상 10월 3~9일 송출CJ대한통운, 우수시장 박람회서 QR 택배·얼굴인식 결제 지원
THE JELIBI BRIEF

인터넷을 너무 많이 보는 팀이 대신 골라 옵니다.

SUBSCRIBE

바로가기 등록하시면, 더 쉽게 찾아보실 수 있습니다.