NOW BUZZING 무역박람회에 AI 비서와 로봇이 등장한 … · 안경이 스니커즈가 되는 중, 진스의 승부… · CGV 10월 특별상영관 라인업, 영화·…◆
JELIBI
⌕ SUBSCRIBE
SEOUL · DAILY · ISSUE No.341 WE TRIED IT · THE PICK · BEHIND IT 2026.11.14 · SAT
JELIBI
⌕ SUB
Beauty Body Gadget Bites Buzz World
HOME/GADGET/BEHIND IT
GADGET BEHIND IT · 5 MIN READ

NVIDIA, AI 추론 소프트웨어 Dynamo 공개
JD 젤리비 편집국 · 2025.07.03 SHARE · COPY LINK

무슨 발표인가

  • Triton Inference Server의 후속 오픈소스 추론 소프트웨어
  • 수천 개 GPU 규모의 추론 통신 오케스트레이션·가속화
  • 처리·생성 단계를 분리해 각 단계별 독립 최적화 가능

현재 이용 가능

원문 (영어)

GTC— NVIDIA today unveiled NVIDIA Dynamo , an open-source inference software for accelerating and scaling AI reasoning models in AI factories at the lowest cost and with the highest efficiency. Efficiently orchestrating and coordinating AI inference requests across a large fleet of GPUs is crucial to ensuring that AI factories run at the lowest possible cost to maximize token revenue generation.

As AI reasoning goes mainstream, every AI model will generate tens of thousands of tokens used to “think” with every prompt. Increasing inference performance while continually lowering the cost of inference accelerates growth and boosts revenue opportunities for service providers.

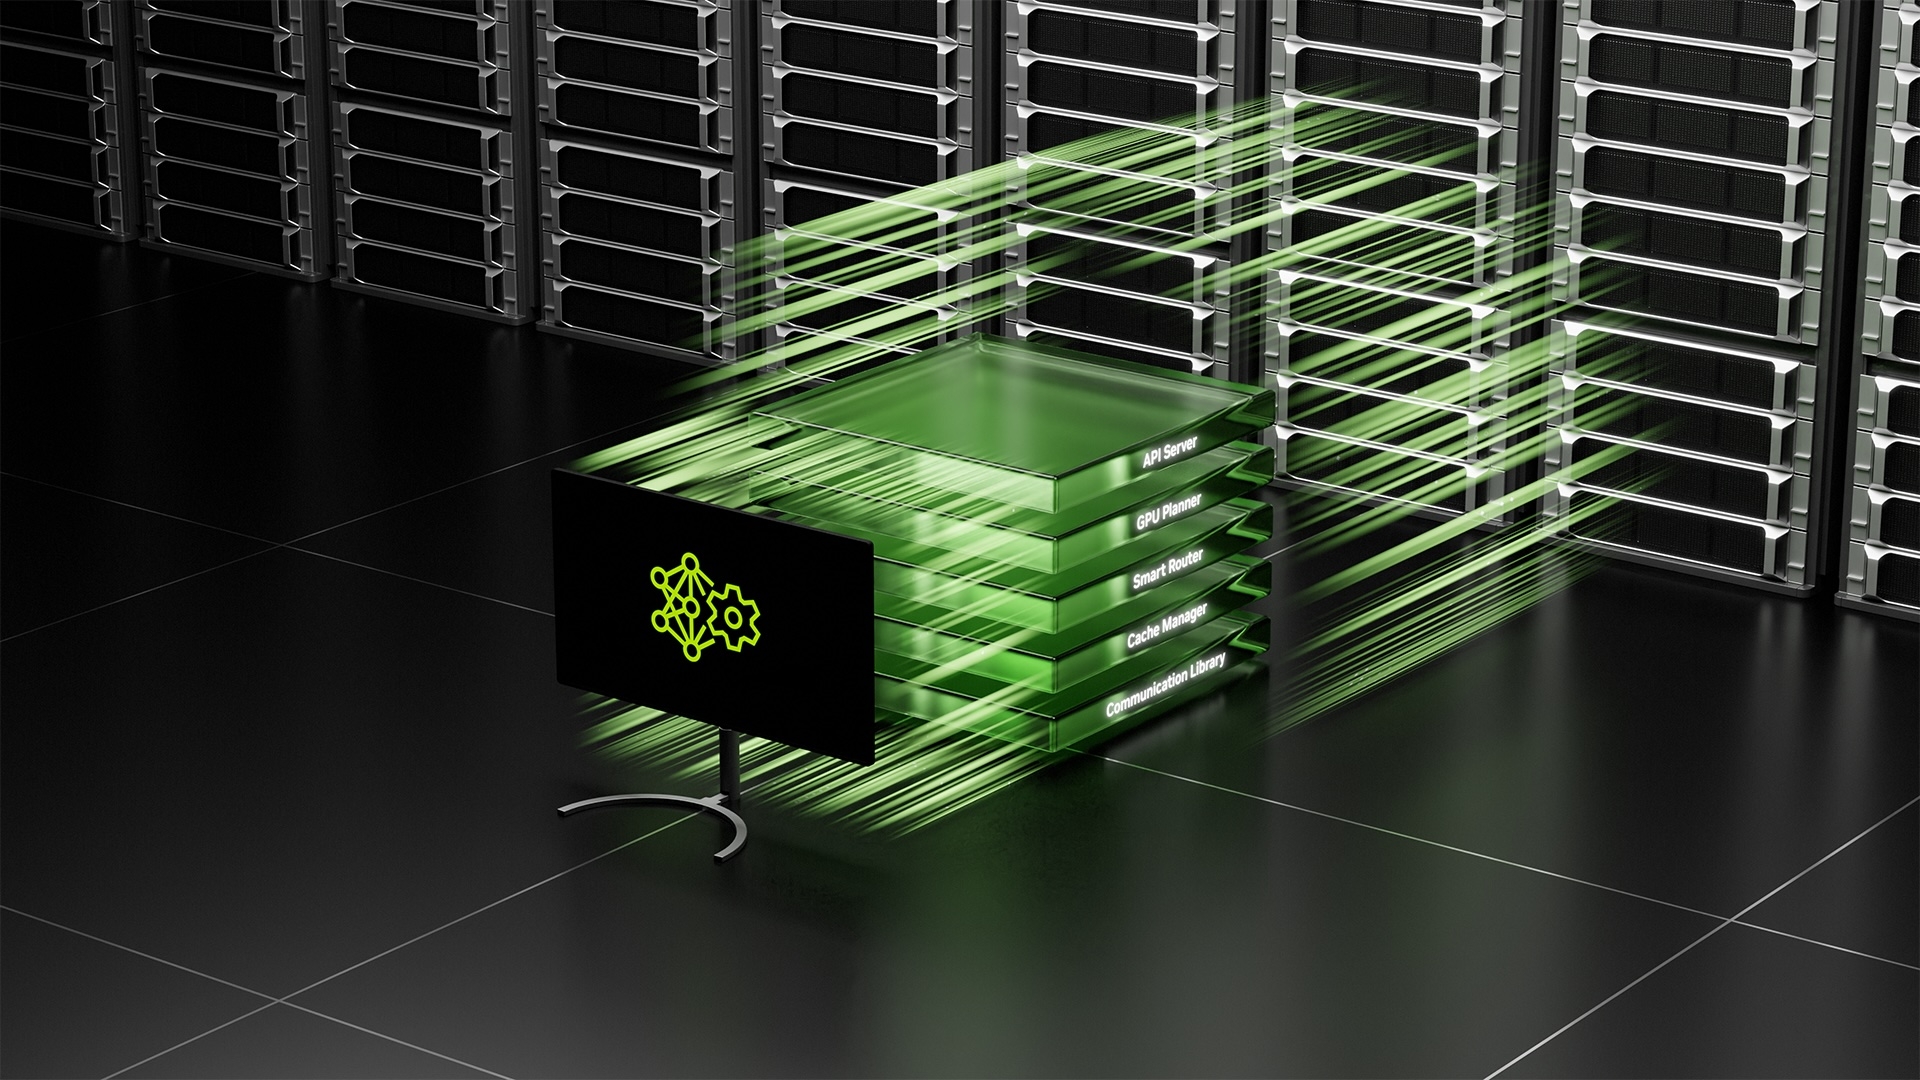
NVIDIA Dynamo, the successor to NVIDIA Triton Inference Server , is new AI inference-serving software designed to maximize token revenue generation for AI factories deploying reasoning AI models. It orchestrates and accelerates inference communication across thousands of GPUs, and uses disaggregated serving to separate the processing and generation phases of large language models (LLMs) on different GPUs.

This allows each phase to be optimized independently for its specific needs and ensures maximum GPU resource utilization. “Industries around the world are training AI models to think and learn in different ways, making them more sophisticated over time,” said Jensen Huang, founder and CEO of NVIDIA.

“To enable a future of custom reasoning AI, NVIDIA Dynamo helps serve these models at scale, driving cost savings and efficiencies across AI factories.” Using the same number of GPUs, Dynamo doubles the performance and revenue of AI factories serving Llama models on today’s NVIDIA Hopper platform.

원문: NVIDIA News — "NVIDIA Dynamo Open-Source Library Accelerates and Scales AI Reasoning Models" (2025-07-03) 공식 원문: https://nvidianews.nvidia.com/news/nvidia-dynamo-open-source-library-accelerates-and-scales-ai-reasoning-models

#NVIDIA News
THE JELIBI BRIEF

A small team that reads too much internet so you don't have to.

SUBSCRIBE →
GADGET

삼성헬스 수면 코칭 업데이트, 데이터 요구사항 완화

GADGET

오픈소스 취약점 스캔 서비스 OSS Scanner 무료 출시

GADGET

메타, 싱가포르 장애인을 위해 AI 안경 1000개 기부

← GADGET BEHIND IT

NVIDIA, AI 추론 소프트웨어 Dynamo 공개

젤리비 편집국·2025.07.03·5 MIN
IN THIS PIECE
무슨 발표인가 원문 (영어)

무슨 발표인가

  • Triton Inference Server의 후속 오픈소스 추론 소프트웨어
  • 수천 개 GPU 규모의 추론 통신 오케스트레이션·가속화
  • 처리·생성 단계를 분리해 각 단계별 독립 최적화 가능

현재 이용 가능

원문 (영어)

GTC— NVIDIA today unveiled NVIDIA Dynamo , an open-source inference software for accelerating and scaling AI reasoning models in AI factories at the lowest cost and with the highest efficiency. Efficiently orchestrating and coordinating AI inference requests across a large fleet of GPUs is crucial to ensuring that AI factories run at the lowest possible cost to maximize token revenue generation.

As AI reasoning goes mainstream, every AI model will generate tens of thousands of tokens used to “think” with every prompt. Increasing inference performance while continually lowering the cost of inference accelerates growth and boosts revenue opportunities for service providers.

NVIDIA Dynamo, the successor to NVIDIA Triton Inference Server , is new AI inference-serving software designed to maximize token revenue generation for AI factories deploying reasoning AI models. It orchestrates and accelerates inference communication across thousands of GPUs, and uses disaggregated serving to separate the processing and generation phases of large language models (LLMs) on different GPUs.

This allows each phase to be optimized independently for its specific needs and ensures maximum GPU resource utilization. “Industries around the world are training AI models to think and learn in different ways, making them more sophisticated over time,” said Jensen Huang, founder and CEO of NVIDIA.

“To enable a future of custom reasoning AI, NVIDIA Dynamo helps serve these models at scale, driving cost savings and efficiencies across AI factories.” Using the same number of GPUs, Dynamo doubles the performance and revenue of AI factories serving Llama models on today’s NVIDIA Hopper platform.

원문: NVIDIA News — "NVIDIA Dynamo Open-Source Library Accelerates and Scales AI Reasoning Models" (2025-07-03) 공식 원문: https://nvidianews.nvidia.com/news/nvidia-dynamo-open-source-library-accelerates-and-scales-ai-reasoning-models

#NVIDIA News
THE JELIBI BRIEF

A small team that reads too much internet so you don't have to.
SUBSCRIBE →
MORE IN BEHIND IT
CJ프레시웨이, 세종파닭 팝업스토어 운영·지역 상생 추진삼성헬스 수면 코칭 업데이트, 데이터 요구사항 완화CGV 10월 특별상영관 라인업, 영화·공연·애니 풍성CGV, 서울 도심 주요 거점서 불꽃축제 영상 10월 3~9일 송출CJ대한통운, 우수시장 박람회서 QR 택배·얼굴인식 결제 지원
THE JELIBI BRIEF

인터넷을 너무 많이 보는 팀이 대신 골라 옵니다.

SUBSCRIBE

바로가기 등록하시면, 더 쉽게 찾아보실 수 있습니다.